Building a football betting model transforms gambling from intuition-driven speculation into systematic, data-informed analysis. The process requires statistical understanding, disciplined data management, and realistic expectations about what models can and cannot achieve. This guide walks through the complete journey from initial concept through practical implementation, using freely available data and tools accessible to anyone willing to invest the time. The goal isn’t to create a perfect prediction machine but to develop a framework that identifies value more consistently than betting without analytical structure.
Defining Your Model’s Purpose
Before touching any data, clarify precisely what your model should accomplish. A model designed to predict match outcomes requires different construction than one focused on over-under goals. A model targeting correct scores differs from one identifying value in handicap markets. Attempting to build something that does everything simultaneously typically produces something that does nothing well.
Start narrow. Perhaps your initial model focuses solely on predicting which Championship matches will produce under 2.5 goals. This constrained scope allows concentrated attention on the specific factors that influence low-scoring matches without distraction from unrelated variables. Success with a narrow model provides foundation for later expansion; failure reveals learning opportunities without wasted breadth.
Consider your betting style when defining purpose. If you prefer live betting, your model needs to incorporate dynamic factors that pre-match-only models ignore. If you focus on accumulators, you might need win probability estimates rather than expected goals. If you target individual match singles, value identification requires different outputs than accumulator-focused approaches. Match model structure to intended use.
Write down your model’s purpose explicitly. “This model will estimate under 2.5 goals probability for Championship matches to identify value bets against bookmaker lines.” Such clarity prevents scope creep and provides success criteria for later evaluation. A model that achieves its stated purpose successfully differs from one that wanders toward tangential goals through undisciplined development.
Gathering and Organising Data
Quality data forms the foundation of any useful model. Football-Data.co.uk provides free downloadable results including goals scored, shots, and bookmaker odds for major European leagues. FBref offers detailed statistics including expected goals, passing networks, and defensive metrics. Understat supplies match-level xG data suitable for trend analysis. Multiple sources cross-referenced provide more reliable inputs than single-source dependency.
Download historical data covering at least two full seasons. Single-season samples suffer from noise; multi-year data reveals patterns that persist across varying conditions. Store data in organised spreadsheet format with consistent column headers enabling automated analysis. Clean any inconsistencies: standardised team names, uniform date formats, and verified numerical accuracy matter for later processing.
Create calculated fields from raw data. Goals per game, xG for and against, home versus away splits, clean sheet percentages, and form indicators all require computation from base statistics. Build these calculations into your spreadsheet so updates propagate automatically when new data arrives. Manual recalculation introduces errors and delays that systematic formulas avoid.
Establish a data update routine. After each matchday, incorporate new results into your dataset. Track not just results but the statistics your model uses as inputs. Consistency in data collection enables consistent model application; sporadic updates undermine the systematic approach that models require. Schedule specific times weekly for data maintenance to ensure discipline persists.
Selecting Predictive Variables
Choose model inputs based on logical connection to your target output combined with empirical performance. For under 2.5 goals prediction, relevant variables might include: team xG averages (for and against), recent form in under markets, head-to-head scoring history, and home-away venue effects. Each variable should have plausible causal connection to low-scoring outcomes.
Avoid excessive variable proliferation. Adding dozens of inputs creates overfitting risk where models memorise historical noise rather than learning genuine patterns. Ten well-chosen variables typically outperform fifty indiscriminate ones. Each additional variable should demonstrably improve prediction on held-out test data before inclusion in final models.
Test individual variables for predictive power before combining them. Does xG against genuinely predict future goal concession? Do teams with high recent under rates continue producing unders? Simple correlation analysis reveals which variables carry signal versus which carry only noise. Discard variables that fail individual tests regardless of intuitive appeal.
Consider variable interactions where relevant. Home advantage might amplify defensive strength effects; fixture timing might interact with squad depth. Modelling interactions requires larger samples to avoid overfitting but can capture dynamics that individual variables miss. Start with main effects only; add interactions once your baseline model demonstrates reasonable performance.
Building the Model Structure
Regression models provide accessible starting points for football betting prediction. Linear regression estimates continuous outcomes like expected goals; logistic regression estimates binary outcomes like win/lose or over/under. Excel’s regression tools handle basic implementations; those comfortable with programming find Python or R offer more sophisticated options.
For a simple under 2.5 goals model, logistic regression works well. Your outcome variable is binary: 1 if the match produced under 2.5 goals, 0 if over. Input variables might include combined team xG averages, home team defensive strength, away team attacking weakness, and recent under form. The regression produces coefficients that weight each variable’s contribution to predicting low-scoring matches.
Convert regression outputs to probabilities using the logistic function. Your model’s probability estimate for under 2.5 becomes the basis for value identification when compared against bookmaker odds. If your model estimates 58% probability while bookmaker odds imply 48%, potential value exists. The magnitude of that gap determines whether the value exceeds transaction costs.
Poisson-based models offer alternative structure particularly suited to goals markets. Rather than predicting binary outcomes, estimate expected goals for each team then use Poisson distribution to generate probability grids across scorelines. This approach produces simultaneous estimates for multiple markets: match result, over/under, correct score, and BTTS all derive from the same underlying goal expectations.
Testing and Validating Your Model
Never evaluate model performance on the same data used for construction. This fundamental error produces overly optimistic assessments that crumble when applied to new matches. Split your dataset: use two-thirds for building the model, reserve one-third for testing. Only performance on the held-out test set indicates genuine predictive capability.
Backtesting against historical betting lines reveals whether your model identifies actual value. Record what your model would have predicted for each historical match, compare against the odds that were available, simulate betting outcomes assuming you placed bets wherever your model showed edge. Profitable backtests suggest genuine predictive ability; unprofitable backtests indicate model failures.
Track calibration alongside profitability. When your model estimates 60% probability, does the event occur approximately 60% of the time across large samples? Miscalibrated models systematically overconfident or underconfident require adjustment. Plot estimated probabilities against actual occurrence rates; the relationship should follow a diagonal line if calibration is correct.
Beware of overfitting during validation. If your model performs dramatically better on training data than test data, it has memorised noise rather than learned patterns. Simplify the model by removing variables until training and test performance converge. Robust models show similar performance across both datasets because they capture genuine predictive relationships.
Refining and Iterating
Initial model versions rarely achieve optimal performance. Refinement cycles improve predictions through careful adjustment based on empirical feedback. Identify where the model fails most dramatically and investigate whether additional variables or structural changes could address those failure modes.
Track errors systematically. When your model confidently predicts under 2.5 and the match produces four goals, analyse what caused the miss. Were key variables unavailable (late injury news)? Was the opposition quality misassessed? Did unusual circumstances (red cards, penalties) distort outcomes in unpredictable ways? Pattern recognition across errors reveals improvement opportunities.
Avoid over-optimising to historical data. Each refinement that improves fit to past matches risks incorporating noise rather than signal. Validate each change on held-out data before accepting it into your model. Changes that improve training performance but degrade test performance indicate overfitting that should be reversed.
Document versions meticulously. Maintain records of what variables each model version included, what coefficients were estimated, and how performance evolved. This documentation enables reverting to earlier versions if later changes prove counterproductive. It also provides learning opportunities when reviewing what worked and what failed across your model development history.
Practical Application Workflow
With a validated model, establish consistent application workflow. Each week, update your data with recent results. Run model predictions for upcoming matches. Compare model outputs against available bookmaker odds. Identify matches where your edge exceeds your threshold (perhaps 3% or 5% depending on risk tolerance).
Calculate stakes using consistent methodology. Kelly Criterion provides mathematical stake sizing based on edge magnitude and probability estimates. More conservative fractional Kelly approaches reduce variance at the cost of slower bankroll growth. Flat staking ignores edge magnitude but provides simplicity and psychological comfort. Whatever approach you choose, apply it consistently.
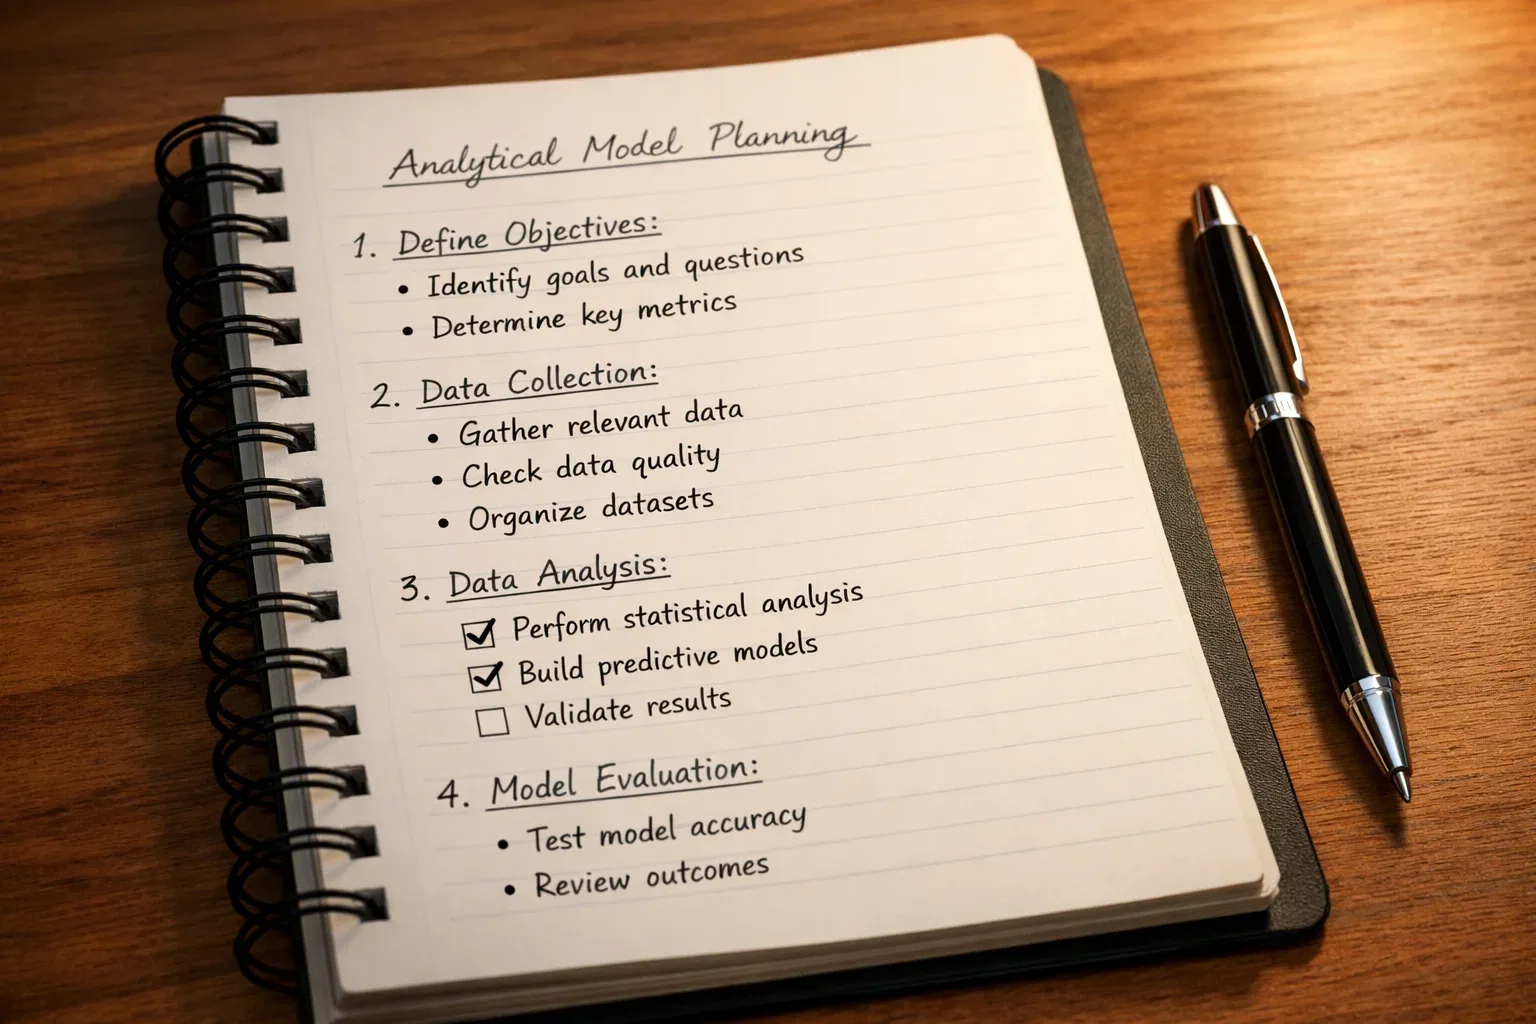
Record each bet with complete details: match, market, stake, odds, and model probability estimate. After matches conclude, record outcomes and calculate returns. Aggregate statistics over time reveal whether your model genuinely produces profit. Without meticulous record-keeping, you cannot distinguish skill from luck or identify systematic model weaknesses.
Schedule periodic model reviews. Monthly assessment of recent performance catches degradation before losses accumulate. Seasonal reviews enable larger-scale adjustments as football patterns evolve. Markets adapt; successful betting approaches attract imitators who erode edge over time. Models require ongoing maintenance rather than one-time construction.
Use proper apps like bet tracking apps.
Common Pitfalls and How to Avoid Them
Overconfidence represents the most dangerous pitfall. First-time modelers often assume their construction produces reliable predictions without adequate validation. Every model contains errors; the question is whether positive edge survives those errors. Maintain humility about what your model can achieve and validate skeptically before risking significant stakes.
Data mining for patterns that don’t generalise destroys bankrolls. With enough variables and historical data, spurious correlations appear that seem predictive but reflect random noise. The fact that teams wearing red historically beat teams wearing blue on Tuesdays in October means nothing for future matches. Require logical justification for any pattern before incorporating it into models.
Ignoring non-statistical factors undermines model application. Your model might correctly identify a match as likely low-scoring based on historical patterns, but if the home team desperately needs a win for promotion and the away team has already secured safety, motivation distorts expected behaviour. Layer contextual judgment onto model outputs rather than betting blindly on quantitative recommendations.
Abandoning models after losing streaks wastes development investment. If your model validated successfully on historical data, short-term losses represent variance rather than fundamental failure. Distinguish between losing streaks within expected variance bounds and systematic underperformance suggesting genuine model problems. The former requires patience; the latter requires investigation.
Scaling and Expanding
Successful narrow models can expand to related markets. An under 2.5 goals model naturally extends to under 1.5 and under 3.5 by adjusting output thresholds. The same expected goals inputs that predict low-scoring matches inform BTTS predictions when reframed around individual team scoring probability. Logical extensions leverage existing work rather than starting from scratch.
Multiple models targeting different markets require portfolio management. If you’re betting under markets, correct scores, and handicaps simultaneously, correlations between positions need consideration. Overexposure to a single match through multiple correlated bets creates risk that individual position sizing doesn’t capture. Think holistically about your total exposure.
Computational sophistication can increase as skills develop. Machine learning approaches like random forests and neural networks potentially outperform simple regression given sufficient data and expertise. However, more complex methods require more data to avoid overfitting and more expertise to implement correctly. Don’t escalate complexity before mastering simpler approaches.
Consider specialisation rather than breadth. Perhaps your model works exceptionally well for Championship matches but poorly for Premier League equivalents. Rather than forcing inferior predictions in the top flight, concentrate resources where your edge is largest. Deep expertise in narrow domains often outperforms shallow competence across broad markets.
The Long-Term Perspective
Building a genuinely profitable football betting model requires months or years of development, not days or weeks. The learning curve is steep; the data requirements are substantial; the validation standards are demanding. Those seeking instant profits will be disappointed. Those willing to invest sustained effort can develop genuine analytical capabilities.
Expect frustration and failure along the way. Early model versions will perform poorly. Apparent breakthroughs will prove illusory. Losing streaks will test conviction in your methodology. This difficulty filters out casual participants, preserving opportunity for those who persist. The edge exists precisely because exploiting it requires work that most won’t undertake.
The skills developed through model building transfer beyond football betting. Data analysis, statistical reasoning, and systematic thinking apply across domains. Even if your betting returns prove modest, the cognitive skills acquired have broader value. The process is educational regardless of financial outcome.
A well-constructed betting model doesn’t guarantee profit but fundamentally changes your relationship with betting from gambling to investing. The analytical framework transforms random wagering into evidence-based decision making. That transformation, more than any specific return figure, represents the ultimate value of building your own football betting model.
Secure awesome ongoing profits from burnley bet.